gemini-3.5-flash
Google. Run in Raw API call.
2 runs on 2 prompts · 50% finished
Results
The best run of each of its 2 tests first, then every other run. Filter them in the explorer
1 finished runs
Numbers: finish rate, cost, wall time, draft scores
- Runs
- 2
- on 2 prompts
- Finished
- 50%
- 1 of 2
- Median cost, finished run
- not recorded
- n=0
- Median wall time, finished run
- 2m 15s
- n=1
- Recorded spend
- $0
- $0 on unfinished runs; 2 without a recorded cost
From the numbers
Set against the other models with at least 3 runs (top or bottom third), and its draft-score ranks within single prompts. Nothing here is averaged across prompts.
Strengths
- Nothing stands out with enough runs to say so.
Weaknesses
- 1 run ended as the model's own failure (DNF, class MODEL)
Best and hardest run
Best run
Picked as its fastest finished run (no scored result yet).
-
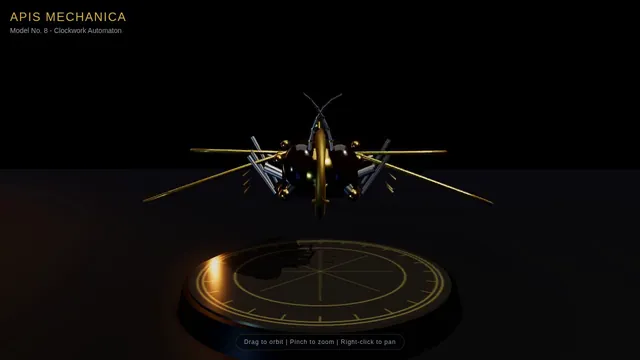
gemini-3.5-flash, raw API call, threejs_mechanical_bee
Raw API call, via Google
raw API baseline
2m 15s
not recorded: the run's token counts were never reported, so there is no estimate
OK
Unscored: no rubric for this prompt
Draft scores by prompt
No scored result yet (only prompts with a published rubric are scored).
By harness
| Raw API call | 2 | 1 | 50% | not recorded: no finished run with a recorded cost | 2m 15s n=1 |
|---|
All 2 tests and experiment collections
- Mechanical bee (1 run)
- Artwork style pass (1 run)
Experiment collections: HTML Files (2) · Three.js (2)