gpt-6.1-sol in Codex CLI 0.156.1
skills off
Zoom, inline player and more ways to view
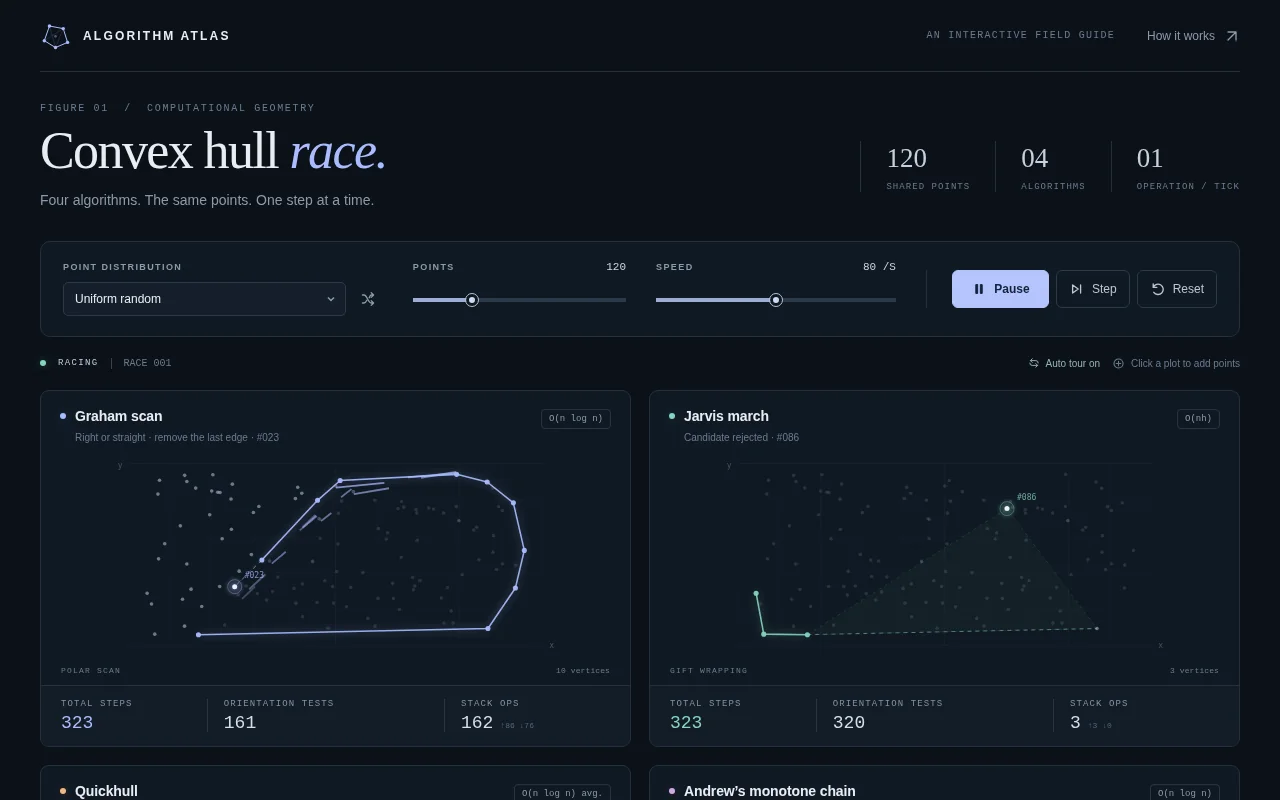
The model's own page, run in a sandboxed frame only when you ask (a page that needs its own origin opens in a new tab on a separate demo site). Phones get a full-screen player capped at 1.5x pixel density (2x on larger screens) so it stays smooth; the original page runs uncapped. Tap inside for sound.
Wall time 31m 21sCost not recorded: the run's token counts were never reported, so there is no estimate
Review
No verdict yet.
The full review
OK. Finished on its own after 31.4 min.
Scores
AI judge
Not scored
No rubric for this prompt
Visitor votes and reviewer grades are not available yet.
- AI judge
- AI judge: the test runner (model claude-opus-5-5), scoring by visual review of the 1600 px render against the pre-registered rubric. No AI-judge score exists for this result: there is no rubric for this prompt, so no score is shown and none is made up.
- Visitors
- Public voting with a blind reveal is coming: you score the output first, then see the other scores.
- Reviewer
- The reviewer's own grade appears here once it is added.
Scores compare results for the same prompt only. AI-judge boards rank runs within one prompt, equal totals sharing a rank; scores from different prompts are never averaged.
Downloads
Files actually published for this run. Original output, site-made previews and post-run conversions are labelled separately.
The exact prompt
as run, 1,979 characters. Every result for this prompt
Build a convex hull algorithm race: four panels (a 2 x 2 grid, stacked on narrow screens) each run a different algorithm on its own copy of the same cloud of 120 random points: Graham scan, Jarvis march (gift wrapping), Quickhull and Andrew's monotone chain. Advance every panel one primitive step per tick (one orientation test, one push or one pop) so the speeds are honestly comparable. Draw the candidate hull growing as glowing edges, flash the point being tested, show rejected points dimming, animate stack pops as edges snapping away, and keep a live counter of orientation tests and stack operations per panel. When a panel finishes, fill its hull with a soft gradient, sweep a highlight around the perimeter and stamp its finishing place. Controls: point-set presets (uniform random, circle with noise, clustered blobs, points on a parabola, nearly collinear), a point-count slider (20 to 400), click or tap to add points, speed slider, play, pause, single step and reset. After each race show a small results table (steps, orientation tests, hull size). So the page is alive without input, on load it starts racing the uniform preset automatically, and after each finish it waits 3 seconds and races the next preset in turn, forever, until the user touches a control. Make it precise and beautiful, like a figure from a great algorithms textbook brought to life.

Save it as index.html in the current directory: one self-contained file with inline CSS and JavaScript only, no libraries or frameworks, and no external requests of any kind (no CDNs, web fonts, images or audio files). It must work when opened directly from disk, fit any window from a 390 px wide phone to a desktop, and run without console errors. You may serve it locally and open it in headless chromium (/usr/bin/chromium, software WebGL, no GPU) to screenshot and inspect your own output, and iterate on your own before finishing. Close any browser you open as soon as you've taken your screenshot.
How it was made
Versions saved during the run
4 intermediate outputs, in the order the model wrote them.


No transcript was delivered with this result.
Cost breakdown
No cost figure: the run's tokens were never reported, so there is nothing to estimate from.
| Tokens by type | Tokens | $ per 1M | Cost |
|---|---|---|---|
| Input (uncached) | 1,496 | n/a | n/a |
| Cache write | 99,932 | n/a | n/a |
| Cache read | 1,355,871 | n/a | n/a |
| Output | 76,505 | n/a | n/a |
- Total computed from tokens
- unknown
- Total reported by the harness
- none
No harness total and no complete list-price estimate. No list price for gpt-6.1-sol in config/prices.json; no estimate computed.
Run notes
- frozen prompt (written): written 2026-10-05 for the MR category expansion (owner request: 500 finished runs in every category); category algorithm_visualizers; zero results
- plain CODEX_HOME copy (config.toml only, run work/ trusted; no AGENTS.md/skills/state)
- Mode: interactive TUI in tmux (160x48), inside bubblewrap sandbox
- Isolation audit: outside paths seen
- Renderer: Canvas 2D (getContext('2d') at index.html line 623) plus DOM/CSS UI and inline SVG; single self-contained index.html, no CDN and no external assets.
- Card video: the run's own session capture (headless Chromium, no GPU), re-encoded as H.264. Poster: the run's own render.png.
- Same frozen prompt as the other rows on this test; configurations differ and all rows are unscored, so this is not a head-to-head result.