Claude Sonnet 5
Anthropic. Run in Raw API call.
99 runs on 99 prompts · 98% finished
Results
The best run of each of its 99 tests first, then every other run. Filter them in the explorer
97 finished runs

Numbers: finish rate, cost, wall time, draft scores
- Runs
- 99
- on 99 prompts
- Finished
- 98%
- 97 of 99
- Median cost, finished run
- not recorded
- n=0
- Median wall time, finished run
- 2m 17s
- n=97
- Recorded spend
- $0
- $0 on unfinished runs; 99 without a recorded cost
From the numbers
Set against the other models with at least 3 runs (top or bottom third), and its draft-score ranks within single prompts. Nothing here is averaged across prompts.
Strengths
- 97 of 99 runs finished: 6th of 24 models with at least 3 (finish rate)
- 2m 17s (n=97): 5th of 23 models with at least 3 (median wall time of a finished run)
Weaknesses
- 2 runs ended as the model's own failure (DNF, class MODEL)
Best and hardest run
Best run
Picked as its fastest finished run (no scored result yet).
-
Claude Sonnet 5, raw API call, Bauhaus Composition
Raw API call, high effort, via Anthropic
raw API baseline
11 s
not recorded: the run's token counts were never reported, so there is no estimate
OK
Unscored: no rubric for this prompt
Hardest run
Picked as its slowest finished run.
-
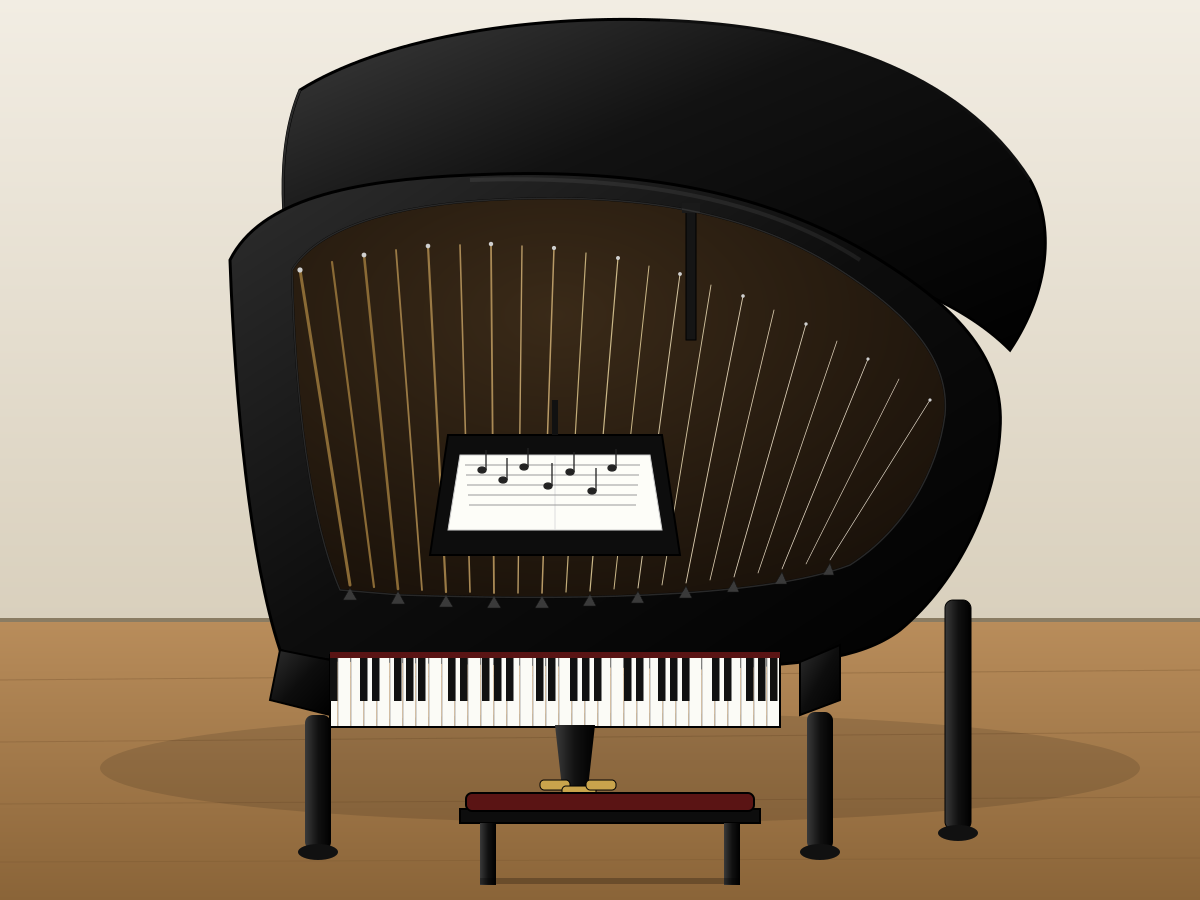
Claude Sonnet 5, raw API call, Grand Piano
Raw API call, high effort, via Anthropic
raw API baseline
7m 22s
not recorded: the run's token counts were never reported, so there is no estimate
OK
Unscored: no rubric for this prompt
Draft scores by prompt
No scored result yet (only prompts with a published rubric are scored).
By harness
| Raw API call | 99 | 97 | 98% | not recorded: no finished run with a recorded cost | 2m 17s n=97 |
|---|
All 99 tests and experiment collections
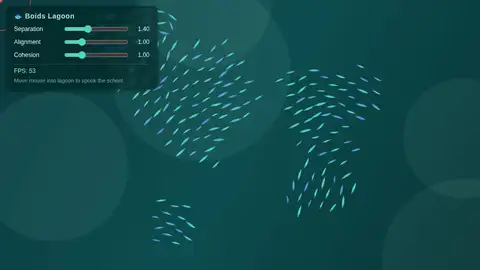
- 019 Boids Lagoon (1 run)
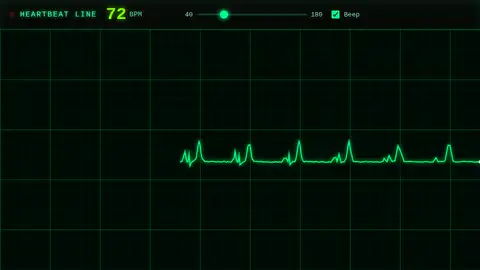
- 016 Heartbeat Line (1 run)
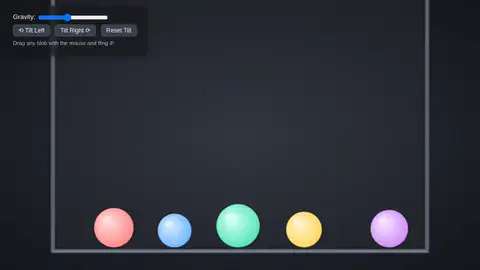
- 013 Soft Body Blobs (1 run)
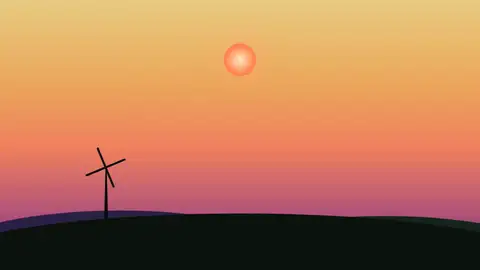
- 011 Pure CSS Sunset (1 run)
- 009 Forest Fire Automaton (1 run)
- 007 Kinetic Headline (1 run)
- 006 Rainfall Bars (1 run)
- 004 Brick Breaker Neon (1 run)
- 002 Pendulum Wave (1 run)
- Grand Piano (1 run)
- Gothic Cathedral Facade (1 run)
- Good Vibes Retro Type (1 run)
- Straw in a Glass (1 run)
- Glitch Text (1 run)
- Victorian Glasshouse (1 run)
- Gardener Watering Plants (1 run)
- Retro Handheld Console (1 run)
- Fractal Tree (1 run)
- Fruit Bowl Still Life (1 run)
- Fountain Pen and Ink (1 run)
- Food Pyramid (1 run)
- Floating Islands (1 run)
- Coffee Decision Flowchart (1 run)
- Flamingo on One Leg (1 run)
- 35mm Film Camera (1 run)
- File Upload Dropzone (1 run)
- Fantasy World Map (1 run)
- Pyramids at Sunset (1 run)
- Basket of Painted Eggs (1 run)
- Windmill by a Canal (1 run)
- Drum Kit (1 run)
- 3D Block Letters (1 run)
- Quadcopter Drone (1 run)
- Dragonfly Over Pond (1 run)
- Dragon Coiled on a Tower (1 run)
- DNA Double Helix (1 run)
- Energy Mix Donut Chart (1 run)
- Festival Oil Lamps (1 run)
- Group Selfie (1 run)
- Noir Detective (1 run)
- Desk Lamp and Books (1 run)
- Desert Dunes at Night (1 run)
- Sales Dashboard Card (1 run)
- Cycling Peloton (1 run)
- Cyberpunk Alley (1 run)
- Corgi Catching a Frisbee (1 run)
- Chalkboard Coffee Lettering (1 run)
- Top-Down City Park (1 run)
- Circuit Board Close-Up (1 run)
- Chessboard Mid-Game (1 run)
- Chef Flipping a Pan (1 run)
- Chat Conversation UI (1 run)
- Container Ship (1 run)
- Canyon River (1 run)
- Campus Map (1 run)
- Calendar Month View (1 run)
- Exploded Burger (1 run)
- Butterfly Life Cycle (1 run)
- Bubble Tea (1 run)
- Breakfast Skillet (1 run)
- Boxing Ring (1 run)
- Bauhaus Composition (1 run)
- Battery Level Icons (1 run)
- Basketball Slam Dunk (1 run)
- Baseball Stadium (1 run)
- Barn Owl in Flight (1 run)
- Ballet Dancer (1 run)
- Fruit Sales Bar Chart (1 run)
- Autumn Forest Path (1 run)
- Bohr Model of an Atom (1 run)
- Stargazer with Telescope (1 run)
- Floating Astronaut (1 run)
- Art Deco Skyscraper (1 run)
- Ant Colony Cutaway (1 run)
- Flat App Icon Set (1 run)
- Illustrated Alphabet A B C (1 run)
- Twin-Bell Alarm Clock (1 run)
- Alien Planet (1 run)
- Acoustic Guitar (1 run)
- 018 Step Sequencer Grid (1 run)
- 017 Typewriter Poem (1 run)
- 015 Color Palette Studio (1 run)
- 014 Snake Reimagined (1 run)
- 012 Magnetic Filings (1 run)
- 010 Toggle Switch Gallery (1 run)
- 008 Pocket Theremin (1 run)
- Chameleon on a Branch (1 run)
- Panda Eating Bamboo (1 run)
- Giraffe Side Profile (1 run)
- Swimming Sea Turtle (1 run)
- Octopus Juggling Teacups (1 run)
- Elephant Calf Mud Bath (1 run)
- Sleeping Curled Cat (1 run)
- Red Fox in Snow (1 run)
- 005 Focus Timer Orbit (1 run)
- 003 Orbital Coffee Landing (1 run)
- Labelled Bicycle Diagram (1 run)
- Koi Pond Garden (1 run)
- 001 Ink Bloom Garden (1 run)
Experiment collections: HTML Files (20) · SVG (79)