gpt-6.1-sol
OpenAI. Run in Codex CLI, Raw API call.
31 runs on 31 prompts · 94% finished
Results
The best run of each of its 31 tests first, then every other run. Filter them in the explorer
29 finished runs
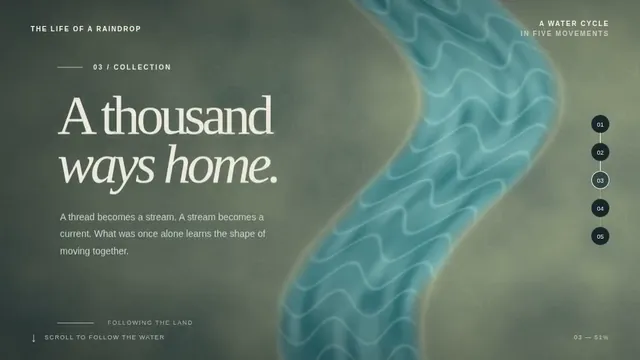 Live demo
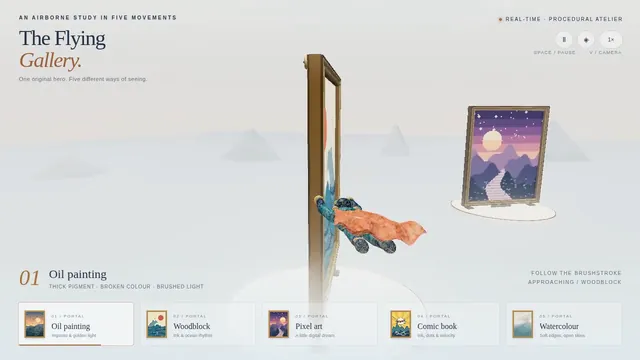 Live scene
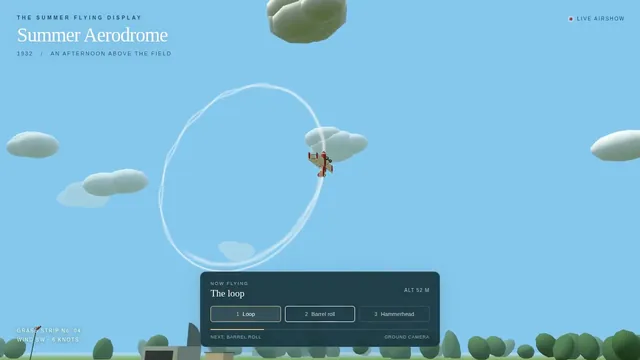 Live scene
Vintage biplane aerobatics over a grass airfield (Three.js)
gpt-6.1-sol
Raw API (one-shot)
raw API baseline
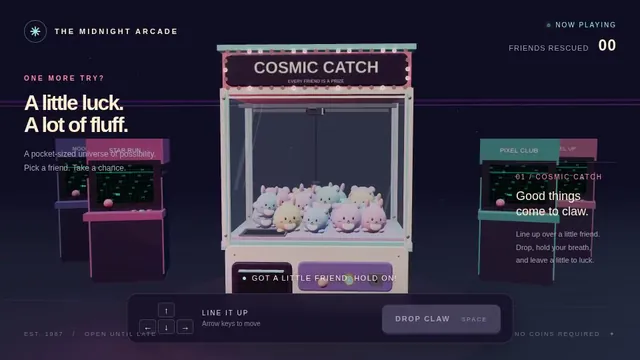 Live scene
Retro arcade claw machine with pastel plush prizes (Three.js)
gpt-6.1-sol
Raw API (one-shot)
raw API baseline
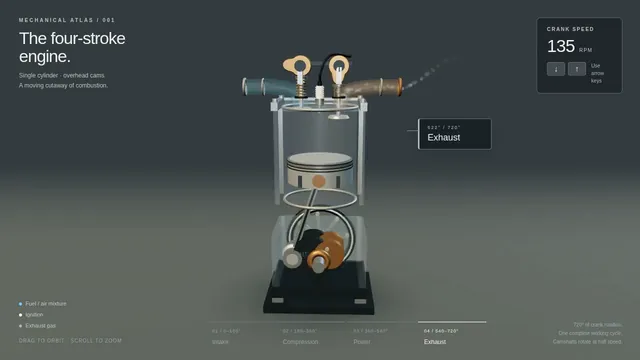 Live scene
Four-stroke engine cutaway: crank, piston and cam-driven valves (Three.js)
gpt-6.1-sol
Raw API (one-shot)
raw API baseline
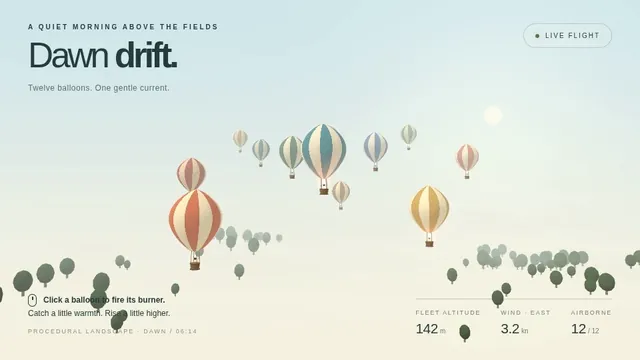 Live scene
Hot air balloon festival over rolling fields (Three.js)
gpt-6.1-sol
Raw API (one-shot)
raw API baseline
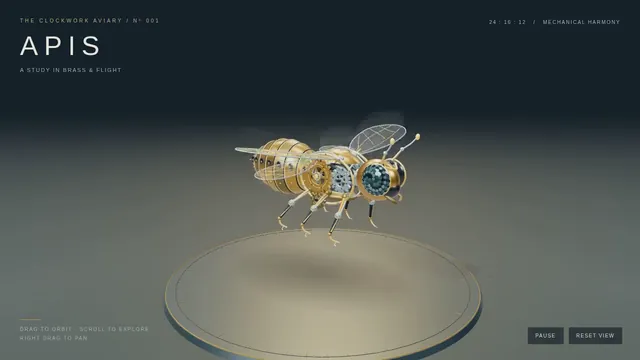 Live scene
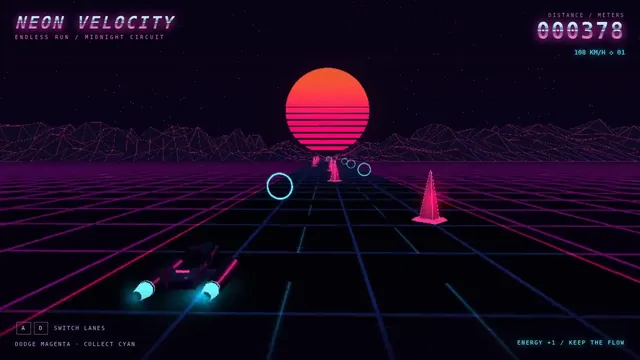 Live scene
Synthwave hover-bike racer on a neon grid highway (Three.js)
gpt-6.1-sol
Raw API (one-shot)
raw API baseline
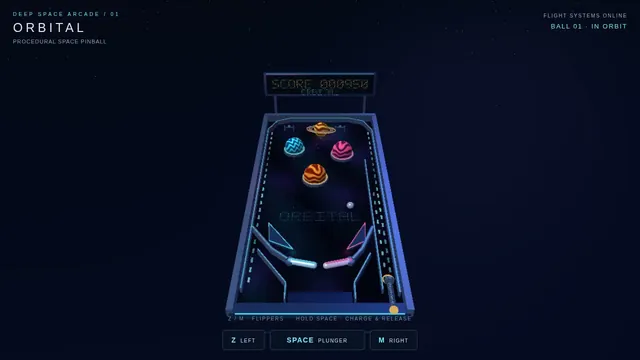 Live scene
Outer-space pinball table with planet bumpers (Three.js)
gpt-6.1-sol
Raw API (one-shot)
raw API baseline
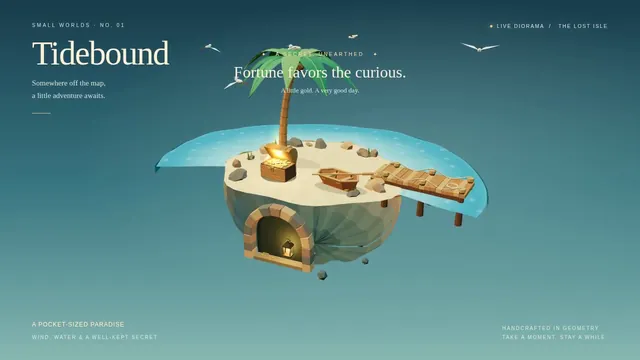 Live scene
Floating pirate island diorama with a cliff cross-section (Three.js)
gpt-6.1-sol
Raw API (one-shot)
raw API baseline
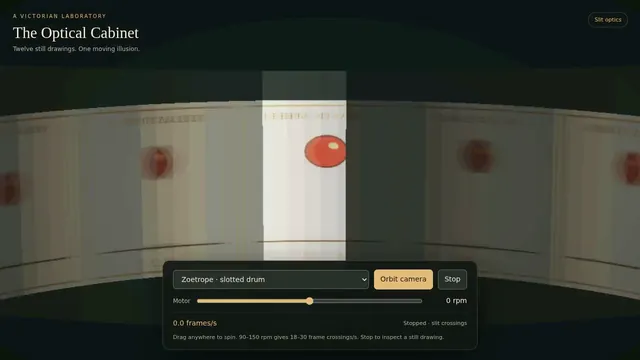 Live scene
Victorian optical toys in 3D: zoetrope, phenakistiscope, praxinoscope (Three.js)
gpt-6.1-sol
Raw API (one-shot)
raw API baseline
 Live demo
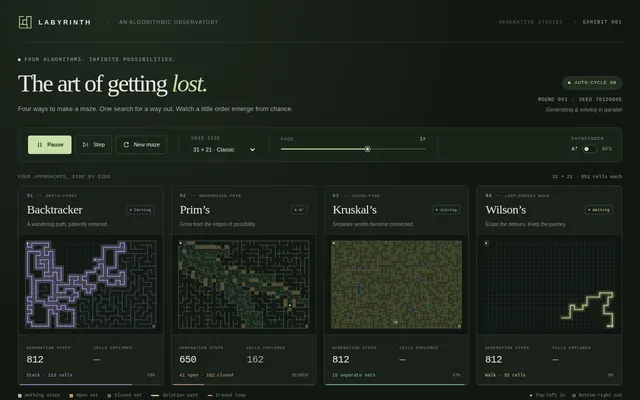 Live demo
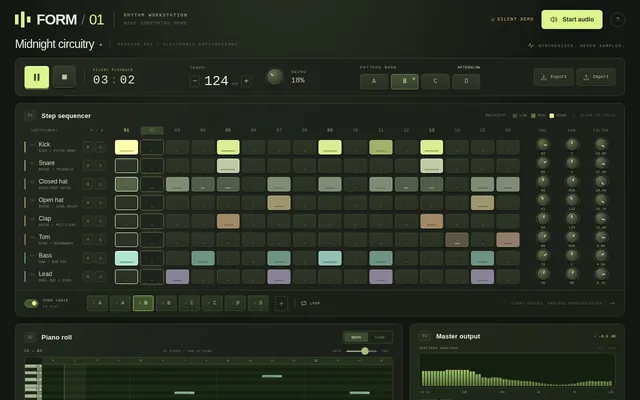 Live demo
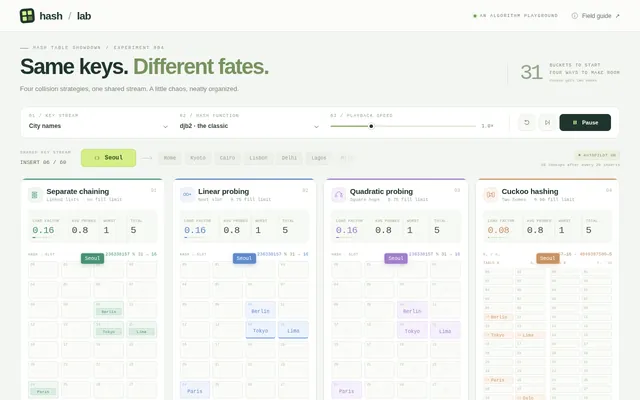 Live demo
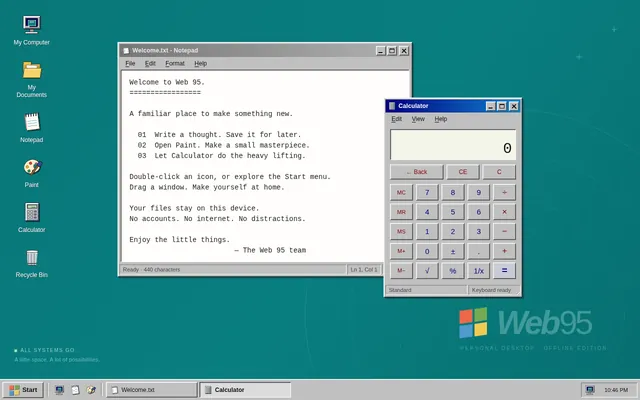 Live demo
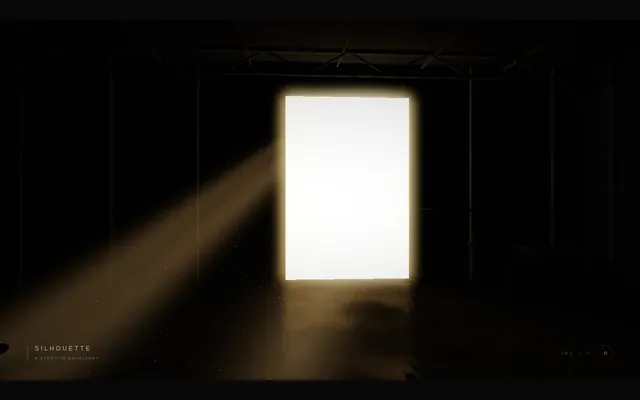 Live scene
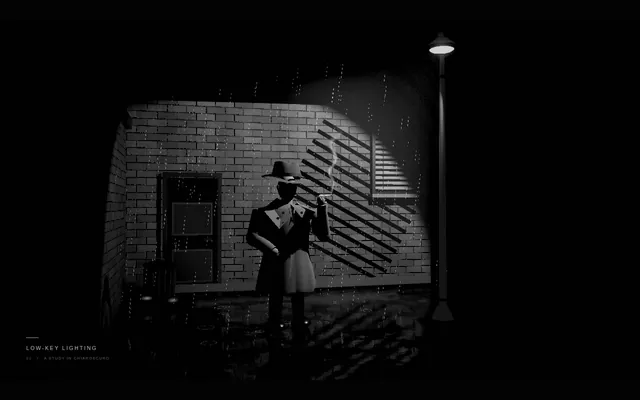 Live scene
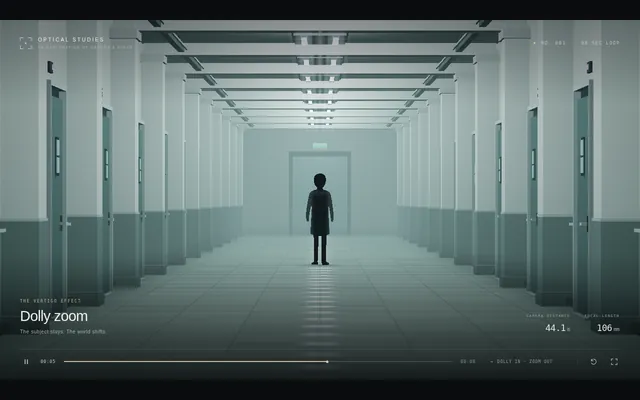 Live scene
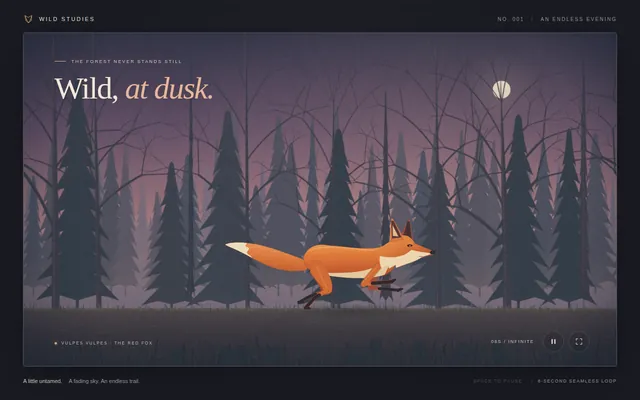 Live scene
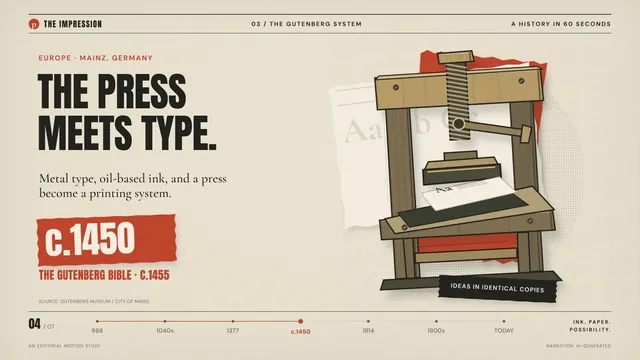 Rendered video
Video printing press collage remotion
gpt-6.1-sol
Codex CLI 0.156.1
skills off
Rendered video from the run
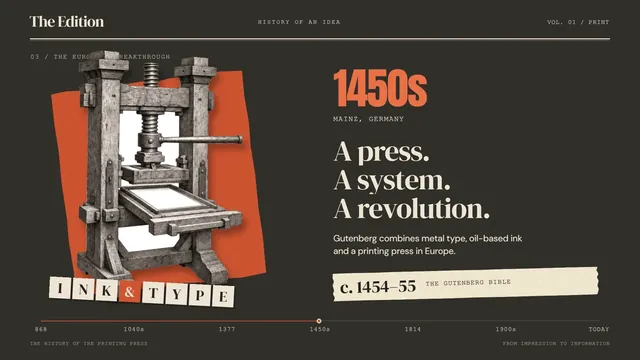 Rendered video
Video printing press collage hyperframes
gpt-6.1-sol
Codex CLI 0.156.1
skills off
Rendered video from the run
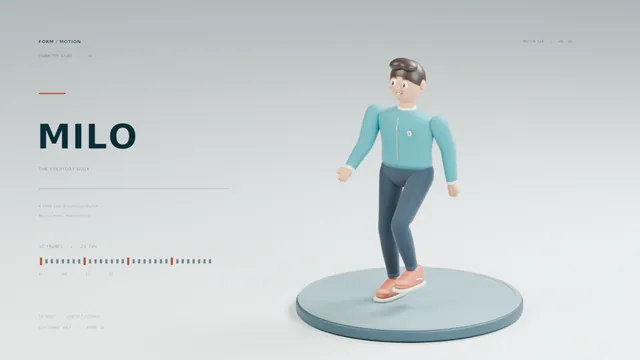
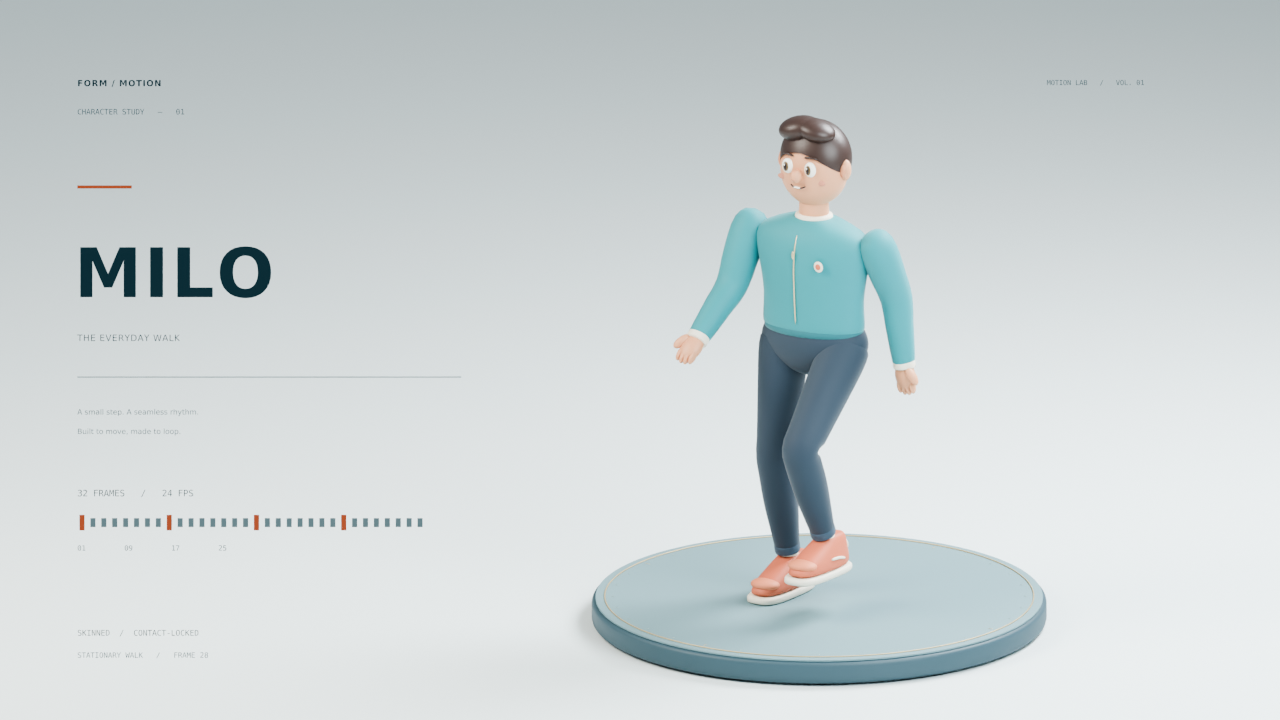
Humanoid walk cycle
gpt-6.1-sol
Codex CLI 0.156.1
skills off
3D model exported by the site · Explore 3D model
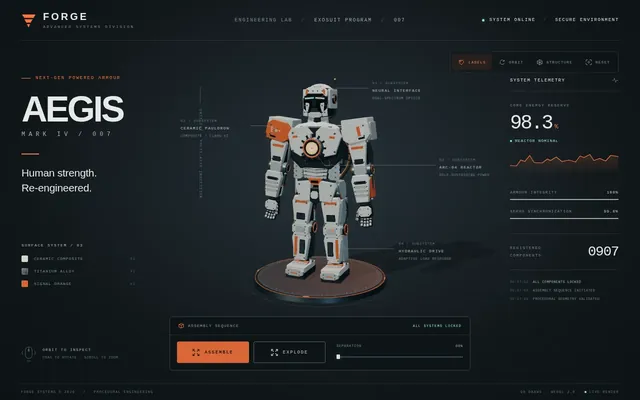 Live scene
Numbers: finish rate, cost, wall time, draft scores
- Runs
- 31
- on 31 prompts
- Finished
- 94%
- 29 of 31
- Median cost, finished run
- not recorded
- n=0
- Median wall time, finished run
- 19m 46s
- n=29
- Recorded spend
- $0
- $0 on unfinished runs; 31 without a recorded cost
From the numbers
Set against the other models with at least 3 runs (top or bottom third), and its draft-score ranks within single prompts. Nothing here is averaged across prompts.
Strengths
- Nothing stands out with enough runs to say so.
Weaknesses
- 19m 46s (n=29): 21st of 23 models with at least 3 (median wall time of a finished run)
- Other unfinished runs, not counted against the model: 2 TIMEOUT
Best and hardest run
Best run
Picked as its fastest finished run (no scored result yet).
-
gpt-6.1-sol, raw API call, Synthwave hover-bike racer on a neon grid highway (Three.js)
Raw API call, via OpenAI
raw API baseline
1m 55s
not recorded: the run's token counts were never reported, so there is no estimate
OK
Unscored: no rubric for this prompt
Hardest run
Picked as its slowest finished run.
-
gpt-6.1-sol, Codex CLI, blender_humanoid_walk_cycle
Codex CLI 0.156.1, max effort, via OpenAI
skills off
1h 33m
not recorded: the run's token counts were never reported, so there is no estimate
OK
Unscored: no rubric for this prompt
Draft scores by prompt
No scored result yet (only prompts with a published rubric are scored).
By harness
| Raw API call | 11 | 11 | 100% | not recorded: no finished run with a recorded cost | 3m 35s n=11 |
|---|---|---|---|---|---|
| Codex CLI | 20 | 18 | 90% | not recorded: no finished run with a recorded cost | 33m 31s n=18 |
All 31 tests and experiment collections
- Codrops-style scroll story: the life of a raindrop (1 run)
- Artwork style pass (1 run)
- Vintage biplane aerobatics over a grass airfield (Three.js) (1 run)
- Retro arcade claw machine with pastel plush prizes (Three.js) (1 run)
- Four-stroke engine cutaway: crank, piston and cam-driven valves (Three.js) (1 run)
- Hot air balloon festival over rolling fields (Three.js) (1 run)
- Mechanical bee (1 run)
- Synthwave hover-bike racer on a neon grid highway (Three.js) (1 run)
- Outer-space pinball table with planet bumpers (Three.js) (1 run)
- Floating pirate island diorama with a cliff cross-section (Three.js) (1 run)
- Victorian optical toys in 3D: zoetrope, phenakistiscope, praxinoscope (Three.js) (1 run)
- Convex hull race (1 run)
- Maze generate and solve (1 run)
- Drum machine daw (1 run)
- Hash table showdown (1 run)
- Retro desktop (1 run)
- Cine silhouette backlight (1 run)
- Cine noir low key (1 run)
- Cine dolly zoom (1 run)
- Fox forest run (1 run)
- Video printing press collage remotion (1 run)
- Video printing press collage hyperframes (1 run)
- Humanoid walk cycle (1 run)
- Procedural armor suit (1 run)
- Creature robot blueprint (1 run)
- Spongebob (1 run)
- Slime softbody (1 run)
- Cine orbit 360 (1 run)
- Game battleship (1 run)
- Stillwater pond (1 run)
- Humanoid motion cycle (1 run)
Experiment collections: HTML Files (22) · Three.js (21) · Blender (2) · Harness lane (31)