Claude Sonnet 5.5
Anthropic. Run in Claude Code, OpenCode, Raw API call. Sonnet 5.5 sweep (2026-09-28): Claude Code and OpenCode, effort max, frozen MR prompts.
84 runs on 69 prompts · 64% finished
Results
The best run of each of its 69 tests first, then every other run. Filter them in the explorer
54 finished runs
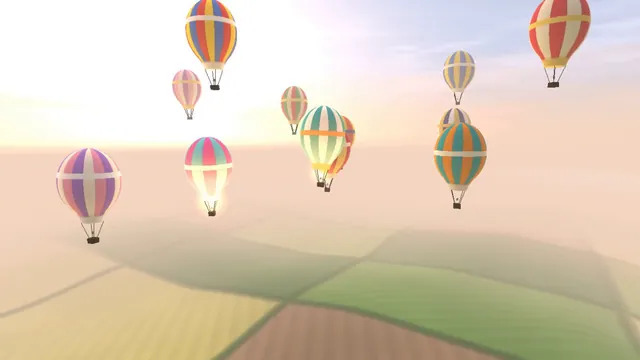 Live scene
Hot air balloon festival over rolling fields (Three.js)
Claude Sonnet 5.5
Raw API (one-shot)
raw API baseline
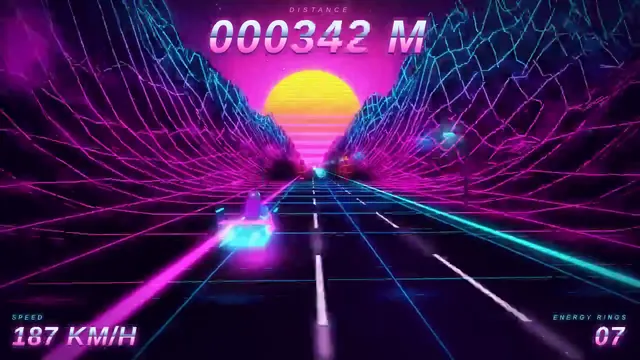 Live scene
Synthwave hover-bike racer on a neon grid highway (Three.js)
Claude Sonnet 5.5
Raw API (one-shot)
raw API baseline
 Live scene
 Live demo
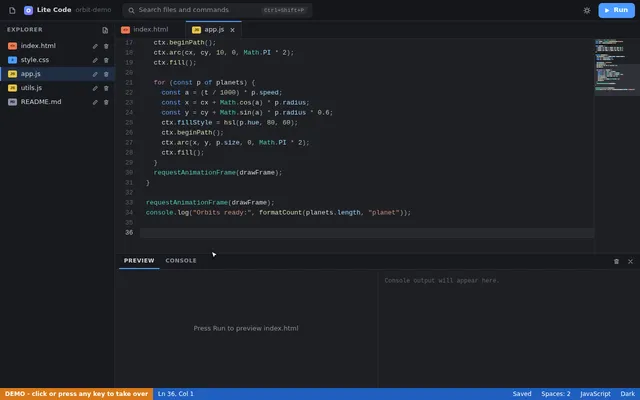 Live demo
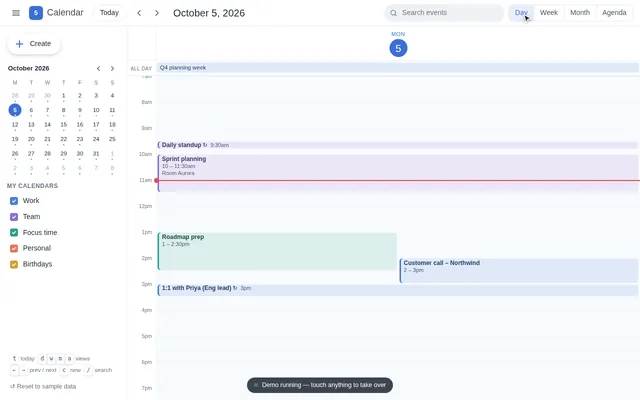 Live demo
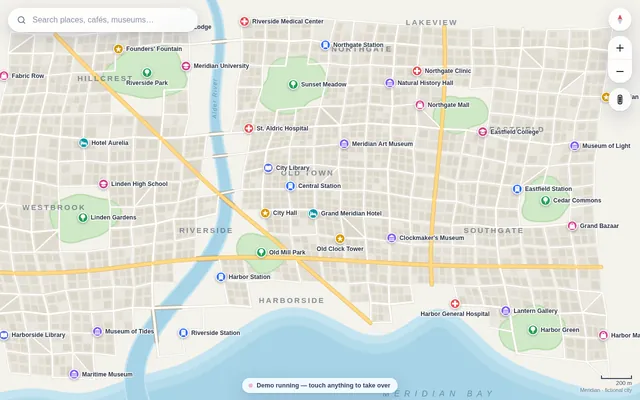 Live demo
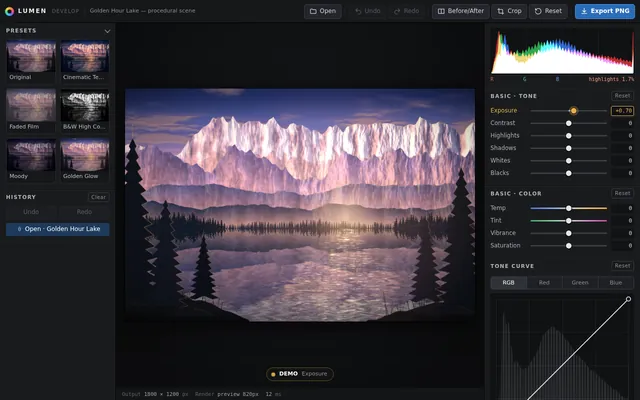 Live demo
 Live demo
 Live demo
 Live demo
 Live demo
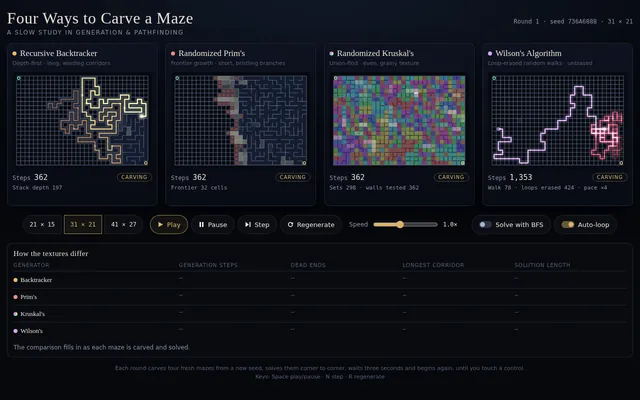 Live demo
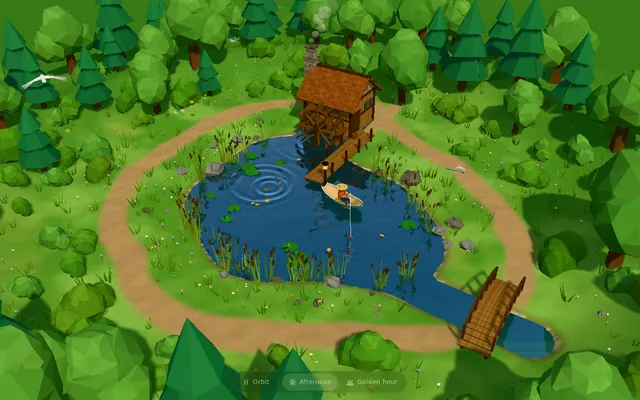 Live scene
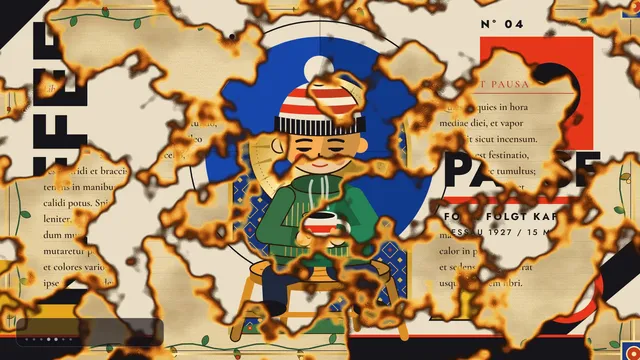 Rendered video
Video style morph character hyperframes
Claude Sonnet 5.5
Claude Code 2.1.280
skills off
Rendered video from the run
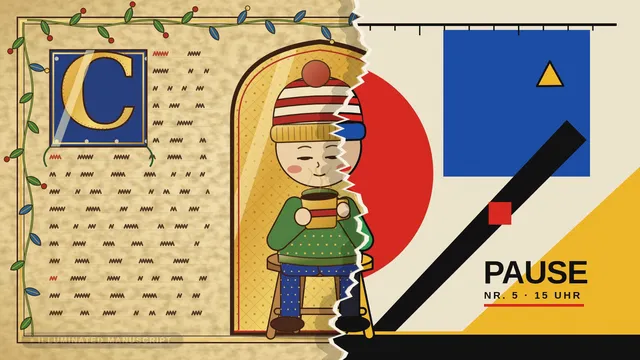 Rendered video
Video style morph character remotion
Claude Sonnet 5.5
Claude Code 2.1.280
skills off
Rendered video from the run
 Live scene
 Live scene
 Live scene
 Live demo
 Live scene
 Live scene
 Live demo
 Live demo
California brown pelican riding a bicycle (detailed spec)
Claude Sonnet 5.5
OpenCode 1.18.33
skills off
Failed · Stopped by our timeout
Lighthouse on a headland at night
Claude Sonnet 5.5
Claude Code 2.1.283
skills off
Failed · Stopped by our timeout
DualSense controller, max fidelity
Claude Sonnet 5.5
OpenCode 1.18.33
skills off
Failed · Stopped by our timeout
Video printing press collage remotion
Claude Sonnet 5.5
Claude Code 2.1.280
skills off
Failed · Stopped by our timeout
No rendered video or project published
How internet works
Claude Sonnet 5.5
Claude Code 2.1.283
skills off
Failed · Stopped by our timeout
Project source only; video not rendered
Isometric SVG town with sprite sheet
Claude Sonnet 5.5
OpenCode 1.18.33
skills off
Failed · Stopped by our timeout
- Post-run video; no posterPost-run video
AI dungeon
Claude Sonnet 5.5
OpenCode 1.18.33
skills off
Failed · Stopped by our timeout
Rendered by the site after the unfinished run
Glass launch UI
Claude Sonnet 5.5
Claude Code 2.1.283
skills off
Failed · Error
Project source only; video not rendered
Bacterium to quantum zoom
Claude Sonnet 5.5
OpenCode 1.18.33
skills off
Failed · Infrastructure failure
Project source only; video not rendered
MacBook Pro 16" realistic 3D render (Playcode benchmark)
Claude Sonnet 5.5
OpenCode 1.18.33
skills off
Failed · Stopped by our timeout
Lighthouse on a headland at night
Claude Sonnet 5.5
OpenCode 1.18.33
skills off
Failed · Stopped by our timeout
DualSense controller, max fidelity
Claude Sonnet 5.5
Claude Code 2.1.283
skills off
Failed · Stopped by our timeout
How internet works
Claude Sonnet 5.5
OpenCode 1.18.33
skills off
Failed · Infrastructure failure
Video not rendered
AI dungeon
Claude Sonnet 5.5
Claude Code 2.1.283
skills off
Failed · Harness and model mismatch
Project source only; video not rendered
Glass launch UI
Claude Sonnet 5.5
OpenCode 1.18.33
skills off
Failed · Infrastructure failure
Video not rendered
Bacterium to quantum zoom
Claude Sonnet 5.5
Claude Code 2.1.283
skills off
Failed · Error
No rendered video or project published
Numbers: finish rate, cost, wall time, draft scores
- Runs
- 84
- on 69 prompts
- Finished
- 64%
- 54 of 84
- Median cost, finished run
- $6.65
- n=10
- Median wall time, finished run
- 26m 03s
- n=54
- Recorded spend
- $177.92
- $117.96 on unfinished runs; 54 without a recorded cost
From the numbers
Set against the other models with at least 3 runs (top or bottom third), and its draft-score ranks within single prompts. Nothing here is averaged across prompts.
Strengths
- Nothing stands out with enough runs to say so.
Weaknesses
- 54 of 84 runs finished: 19th of 24 models with at least 3 (finish rate)
- 26m 03s (n=54): 22nd of 23 models with at least 3 (median wall time of a finished run)
- $6.65 (n=10): 14th of 14 models with at least 3 (median cost of a finished run)
- 2 runs ended as the model's own failure (DNF, class MODEL)
- Other unfinished runs, not counted against the model: 1 HARNESS, 3 INFRA, 18 TIMEOUT, 6 ERROR
Best and hardest run
Best run
Picked as its fastest finished run (no scored result yet).
-
Claude Sonnet 5.5, raw API call, Hot air balloon festival over rolling fields (Three.js)
Raw API call, via Anthropic
raw API baseline
3m 59s
not recorded: the run's token counts were never reported, so there is no estimate
OK
Unscored: no rubric for this prompt
Hardest run
Picked as its costliest run that did not finish.
-
Did not finish · re-run queued
Claude Sonnet 5.5, OpenCode, California brown pelican riding a bicycle (detailed spec)
OpenCode 1.18.33, max effort, via Anthropic
skills off
Stopped (our timeout)
46m 06s $11.28 reported by OpenCode
Draft scores by prompt
No scored result yet (only prompts with a published rubric are scored).
By harness
| Claude Code | 62 | 48 | 77% | $6.65 n=6 | 25m 20s n=48 |
|---|---|---|---|---|---|
| Raw API call | 4 | 2 | 50% | not recorded: no finished run with a recorded cost | 4m 30s n=2 |
| OpenCode | 18 | 4 | 22% | $6.56 n=4 | 37m 09s n=4 |
All 69 tests and experiment collections
- Hot air balloon festival over rolling fields (Three.js) (1 run)
- Synthwave hover-bike racer on a neon grid highway (Three.js) (1 run)
- Soap bubble shader playground (1 run)
- Edit distance dp (1 run)
- Code editor (1 run)
- Calendar planner (1 run)
- Photo editor (1 run)
- Team chat (1 run)
- Drum machine daw (1 run)
- Convex hull race (1 run)
- Kanban board (1 run)
- Maze generate and solve (1 run)
- Stillwater pond (1 run)
- Video style morph character hyperframes (1 run)
- Video style morph character remotion (1 run)
- Toy pool water (1 run)
- Gerstner ocean storm (1 run)
- Gpgpu galaxy collision (1 run)
- Firstprinciples mascot multimedia (1 run)
- Infinite terrain flyover (1 run)
- Jetski ocean physics (1 run)
- Coffee chain sales (1 run)
- Pathfinding race (1 run)
- Sorting race (1 run)
- Retro desktop (1 run)
- Spreadsheet (1 run)
- Cine whip pan (1 run)
- Cine rack focus (1 run)
- Cine crane rise (1 run)
- Cine low angle hero (1 run)
- Cine silhouette backlight (1 run)
- Cine noir low key (1 run)
- Cine dolly zoom (1 run)
- Fox forest run (1 run)
- Humanoid motion cycle (1 run)
- Spongebob (1 run)
- Video printing press collage hyperframes (1 run)
- BMW M4 Competition, side view (flat vector) (2 runs)
- Animated pelican riding a bicycle (SMIL/CSS) (2 runs)
- Xbox 360 controller (2 runs)
- MacBook Pro 16" realistic 3D render (Playcode benchmark) (2 runs)
- Pelican riding a bicycle (control) (2 runs)
- Cine tracking shot (1 run)
- Cine orbit 360 (1 run)
- Procedural armor suit (1 run)
- Creature robot blueprint (1 run)
- Slime softbody (1 run)
- Game battleship (1 run)
- Ant vs gardener (1 run)
- Folding road (1 run)
- Fjord scene (Three.js) (2 runs)
- California brown pelican riding a bicycle (detailed spec) (1 run)
- Pixel lofi loop (2 runs)
- Lighthouse on a headland at night (2 runs)
- DualSense controller, max fidelity (2 runs)
- Artwork style pass (1 run)
- Mechanical bee (1 run)
- Humanoid walk cycle (1 run)
- Video printing press collage remotion (1 run)
- X16 engine (1 run)
- Coastal shallows (1 run)
- Animated short (HTML/JS) (2 runs)
- How internet works (2 runs)
- Isometric SVG town with sprite sheet (2 runs)
- AI dungeon (2 runs)
- Glass launch UI (2 runs)
- Bacterium to quantum zoom (2 runs)
Experiment collections: HTML Files (37) · SVG (17) · Three.js (33) · Blender (2) · Harness lane (84)