GPT-6 Sol
OpenAI. Run in Codex CLI, Raw API call. Run in Codex CLI (its home harness) from 2026-09-25.
238 runs on 234 prompts · 100% finished
Results
The best run of each of its 234 tests first, then every other run. Filter them in the explorer
238 finished runs
Numbers: finish rate, cost, wall time, draft scores
- Runs
- 238
- on 234 prompts
- Finished
- 100%
- 238 of 238
- Median cost, finished run
- $1.31
- n=104
- Median wall time, finished run
- 2m 25s
- n=238
- Recorded spend
- $153.40
- $0 on unfinished runs; 134 without a recorded cost
From the numbers
Set against the other models with at least 3 runs (top or bottom third), and its draft-score ranks within single prompts. Nothing here is averaged across prompts.
Strengths
- 238 of 238 runs finished: 1st of 24 models with at least 3 (finish rate)
- 2m 25s (n=238): 7th of 23 models with at least 3 (median wall time of a finished run)
Weaknesses
- $1.31 (n=104): 11th of 14 models with at least 3 (median cost of a finished run)
Best and hardest run
Best run
Picked as its fastest finished run (no scored result yet).
-
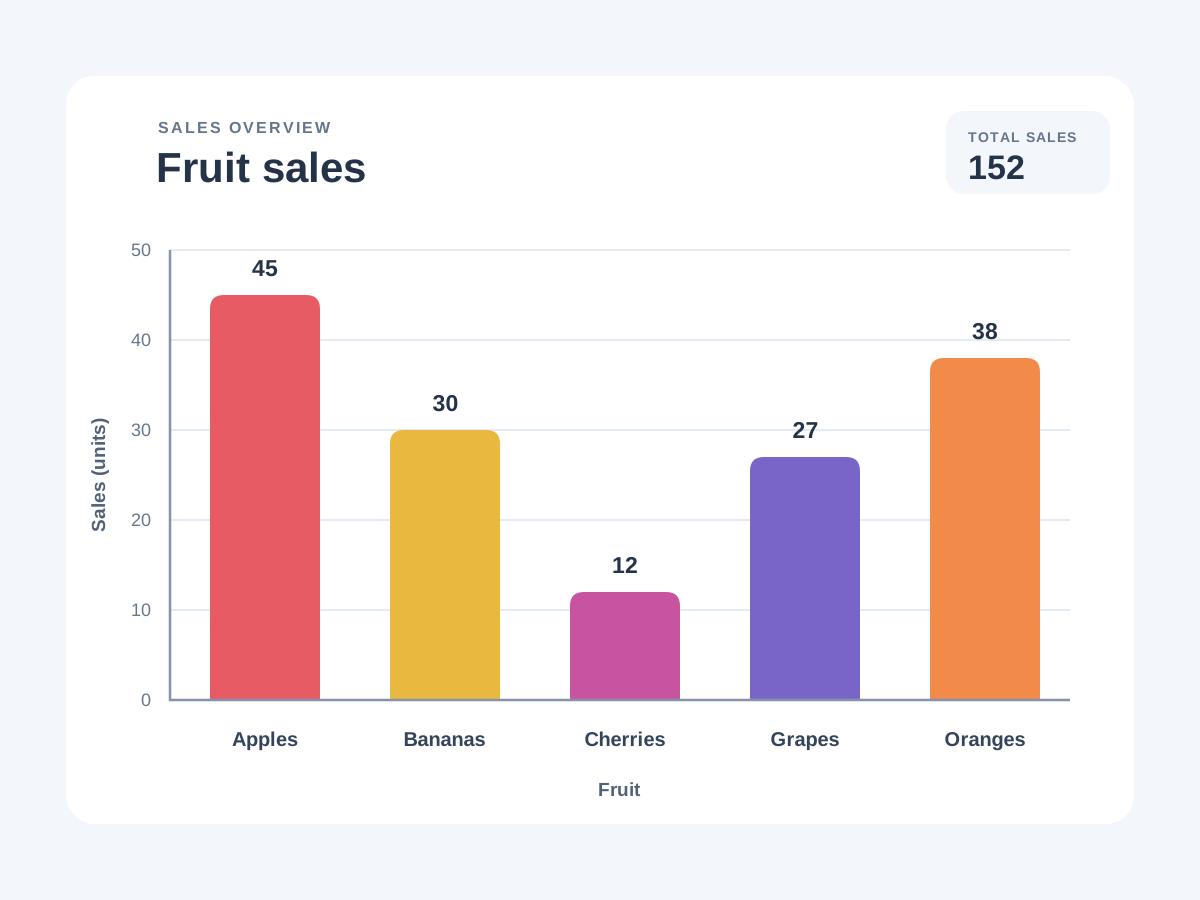
GPT-6 Sol, raw API call, Fruit Sales Bar Chart
Raw API call, high effort, via OpenAI
raw API baseline
30 s
not recorded: the run's token counts were never reported, so there is no estimate
OK
Unscored: no rubric for this prompt
Hardest run
Picked as its slowest finished run.
-
GPT-6 Sol, Codex CLI, cine_tracking_shot
Codex CLI 0.156.1, max effort, via OpenAI
skills off
35m 07s
$2.62 estimated
OK
Unscored: no rubric for this prompt
Draft scores by prompt
No scored result yet (only prompts with a published rubric are scored).
By harness
| Raw API call | 139 | 139 | 100% | $0.44 n=5 | 1m 54s n=139 |
|---|---|---|---|---|---|
| Codex CLI | 99 | 99 | 100% | $1.36 n=99 | 9m 44s n=99 |
All 234 tests and experiment collections
- Sorting race (1 run)
- Pathfinding race (1 run)
- Zoom to the Atom (1 run)
- 017 Typewriter Poem (1 run)
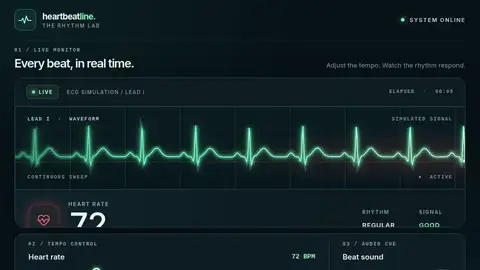
- 016 Heartbeat Line (1 run)
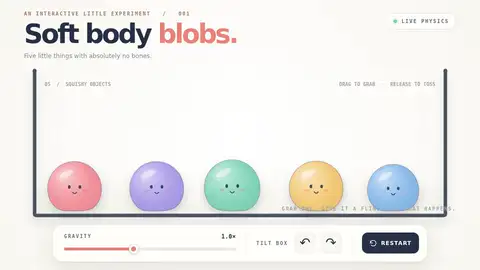
- 013 Soft Body Blobs (1 run)
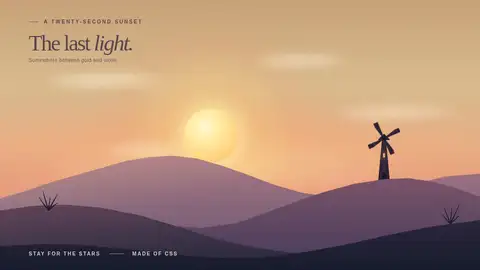
- 011 Pure CSS Sunset (1 run)
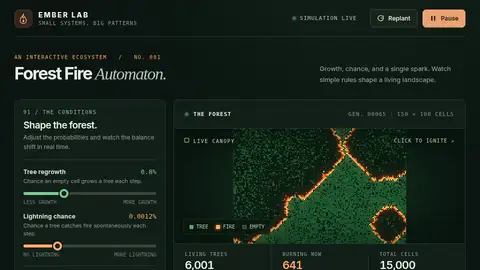
- 009 Forest Fire Automaton (1 run)
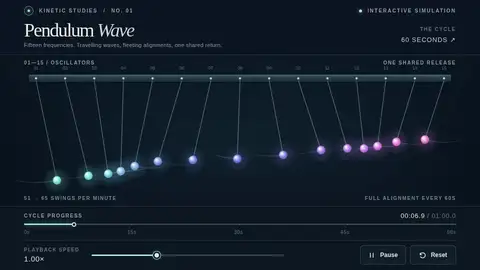
- 002 Pendulum Wave (1 run)
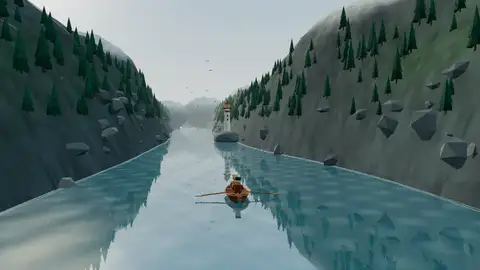
- Fjord scene (Three.js) (2 runs)
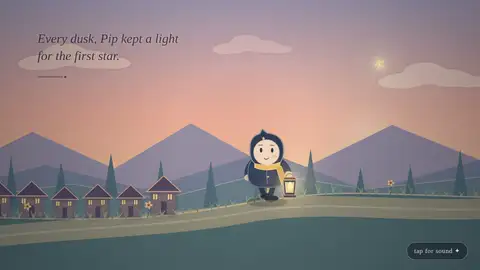
- Animated short (HTML/JS) (3 runs)
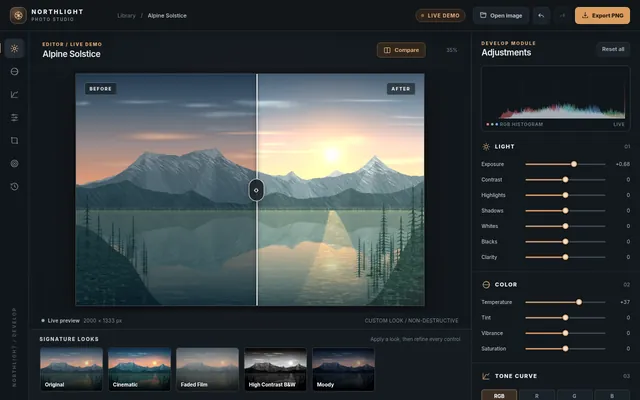
- Photo editor (1 run)
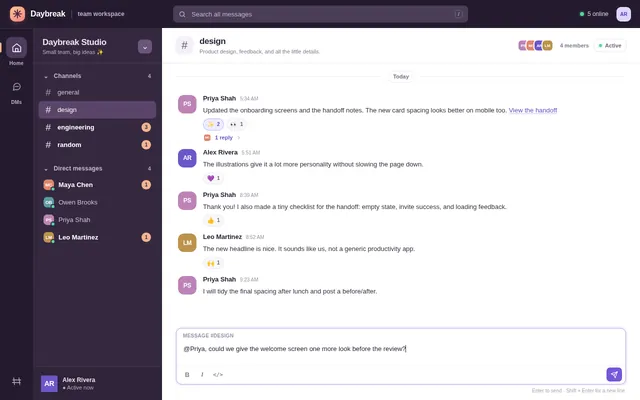
- Team chat (1 run)
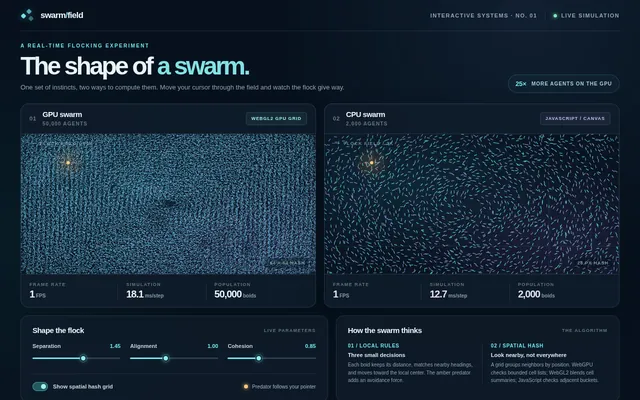
- GPU boids 50k (1 run)
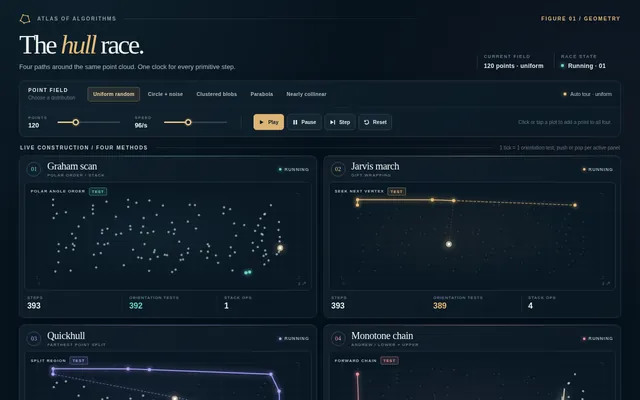
- Convex hull race (1 run)
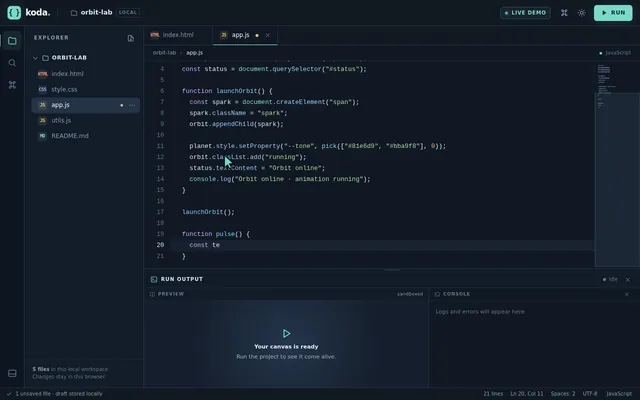
- Code editor (1 run)
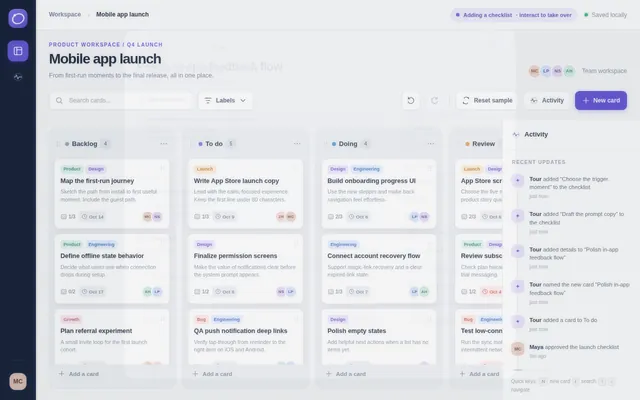
- Kanban board (1 run)
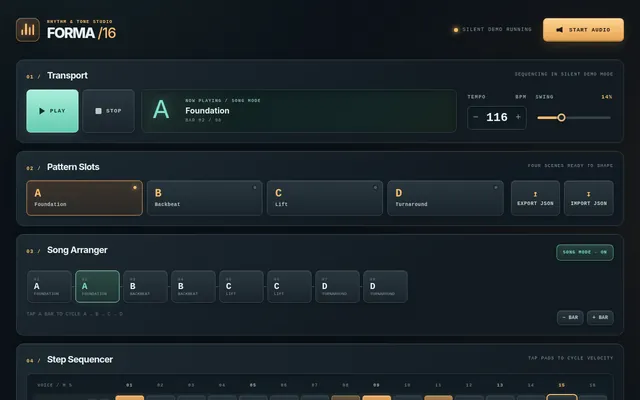
- Drum machine daw (1 run)
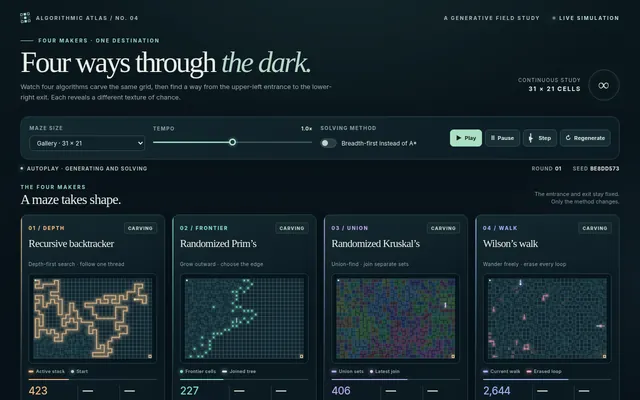
- Maze generate and solve (1 run)
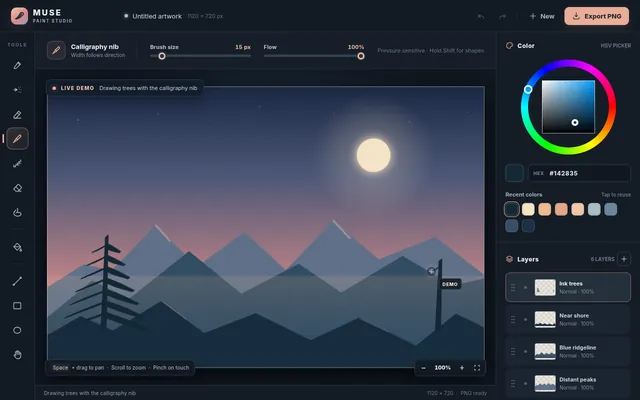
- Paint studio (1 run)
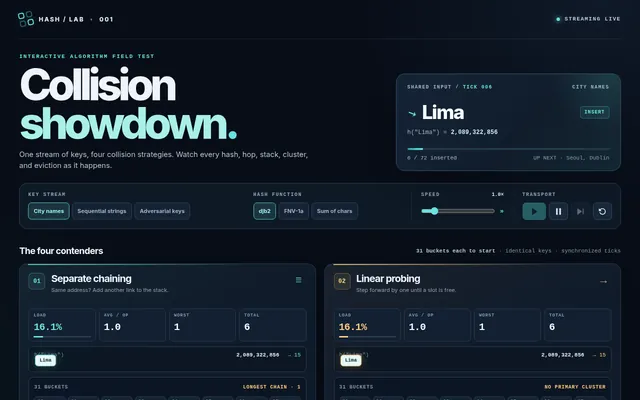
- Hash table showdown (1 run)
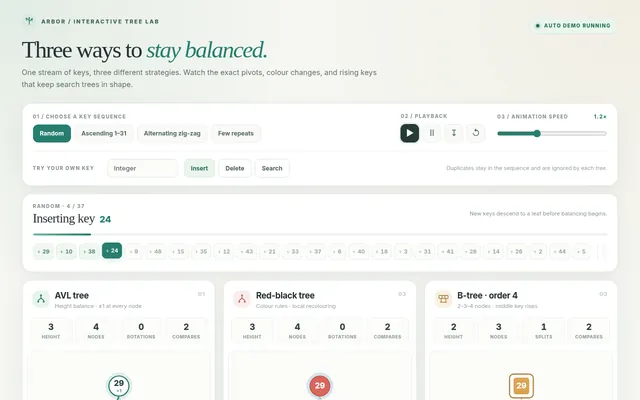
- Balanced trees (1 run)
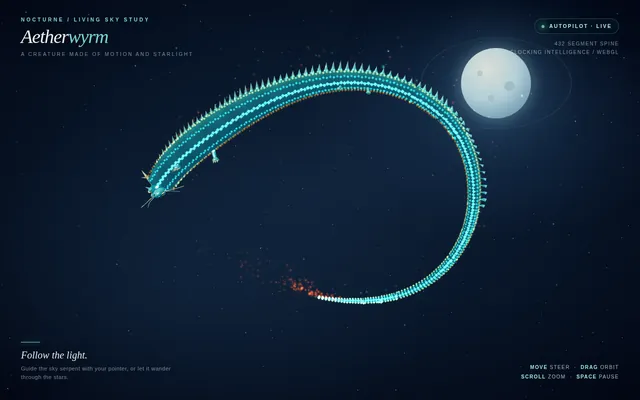
- Boids dragon (1 run)
- Procedural lego builder (1 run)
- Volumetric raymarched sun (1 run)
- Js13k style shader game (1 run)
- Pathtraced product shot (1 run)
- Image to procedural threejs scene (1 run)
- Webgl particle life sim (1 run)
- Rocket car arena (1 run)
- Webgl reaction diffusion coral (1 run)
- One key rhythm runner (1 run)
- Marble run machine (1 run)
- Solar sail orrery (1 run)
- Shader hero background studio (1 run)
- Webgpu ascii shader scene (1 run)
- Torchlit dungeon dragon (1 run)
- Tiny anime world (1 run)
- Webgpu ink marbling (1 run)
- Ps1 horror kitchen (1 run)
- Domino chain physics (1 run)
- Evolving art garden (1 run)
- Threelab breed generative art (1 run)
- One prompt 3D kart racer (1 run)
- Webgpu ocean wave physics (1 run)
- Webgpu snow physics (1 run)
- Webgpu particle life audio (1 run)
- Webgpu sailing storm (1 run)
- Webgpu fishing game (1 run)
- 15-second motion showreel (1 run)
- Collision music machine (1 run)
- Webgpu deferred sponza playground (1 run)
- Train window through four seasons (1 run)
- Token bucket explainer (1 run)
- Recursion explainer (1 run)
- Santa Monica particle beach (1 run)
- "Make a Tron game" (1 run)
- 16-bit pixel wizard sprite loop (1 run)
- Van Gogh cat-spotting game (1 run)
- AI data centre, inside view (1 run)
- Brutalist event promo (1 run)
- CSS 3D cube gallery (1 run)
- Isometric server room (1 run)
- Glass dashboard launch (1 run)
- Terminal hacker boot (1 run)
- Lighthouse storm (1 run)
- Product reveal watch (1 run)
- Ink brush dragon (1 run)
- Chess famous game (1 run)
- Satellite constellation (1 run)
- Sorting algorithms race (1 run)
- Energy mix sankey (1 run)
- Music visualizer synthwave (1 run)
- Github contrib wrapped (1 run)
- Galaxy collision (1 run)
- Chip fabrication journey (1 run)
- Orbital launch sequence (1 run)
- F1 lap telemetry (1 run)
- Tokyo neon title (1 run)
- Stillwater pond (1 run)
- Spreadsheet (1 run)
- Retro desktop (1 run)
- Coffee chain sales (1 run)
- Cine silhouette backlight (1 run)
- Cine dutch angle (1 run)
- Cine noir low key (1 run)
- Cine dolly zoom (1 run)
- Fox forest run (1 run)
- Latte Art (1 run)
- Ladybug on a Leaf (1 run)
- Knight in Armour (1 run)
- Kingfisher Diving (1 run)
- Kids Building a Snowman (1 run)
- Ring of Keys (1 run)
- Seigaiha Wave Pattern (1 run)
- Five-Storey Pagoda (1 run)
- Jack-o'-Lanterns (1 run)
- Isometric Space Station (1 run)
- Isometric Workspace (1 run)
- Isometric Harbour (1 run)
- Isometric Farm (1 run)
- Isometric Cube Illusion (1 run)
- Isometric Coffee Shop (1 run)
- Geometric Star Tiling (1 run)
- Melting Ice Cream Cone (1 run)
- Human Skeleton (1 run)
- Human Heart Anatomy (1 run)
- Human Eye Diagram (1 run)
- Hourglass (1 run)
- Hot Air Balloons (1 run)
- Honeybee on Honeycomb (1 run)
- Hello Neon Sign (1 run)
- Rescue Helicopter (1 run)
- Over-Ear Headphones (1 run)
- Hand Holding Five Fruits (1 run)
- Drippy BOO Lettering (1 run)
- Greek Temple (1 run)
- Grand Piano (1 run)
- Gothic Cathedral Facade (1 run)
- Good Vibes Retro Type (1 run)
- Glitch Text (1 run)
- Straw in a Glass (1 run)
- Victorian Glasshouse (1 run)
- Gardener Watering Plants (1 run)
- Retro Handheld Console (1 run)
- Fruit Bowl Still Life (1 run)
- Fractal Tree (1 run)
- Fountain Pen and Ink (1 run)
- Food Pyramid (1 run)
- Coffee Decision Flowchart (1 run)
- Floating Islands (1 run)
- Flamingo on One Leg (1 run)
- 35mm Film Camera (1 run)
- File Upload Dropzone (1 run)
- Fantasy World Map (1 run)
- Pyramids at Sunset (1 run)
- Basket of Painted Eggs (1 run)
- Windmill by a Canal (1 run)
- Drum Kit (1 run)
- Quadcopter Drone (1 run)
- 3D Block Letters (1 run)
- Dragonfly Over Pond (1 run)
- Dragon Coiled on a Tower (1 run)
- Energy Mix Donut Chart (1 run)
- DNA Double Helix (1 run)
- Festival Oil Lamps (1 run)
- Group Selfie (1 run)
- Noir Detective (1 run)
- Desk Lamp and Books (1 run)
- Desert Dunes at Night (1 run)
- Sales Dashboard Card (1 run)
- Cycling Peloton (1 run)
- Cyberpunk Alley (1 run)
- Chalkboard Coffee Lettering (1 run)
- Top-Down City Park (1 run)
- Circuit Board Close-Up (1 run)
- Chessboard Mid-Game (1 run)
- Chef Flipping a Pan (1 run)
- Chat Conversation UI (1 run)
- Container Ship (1 run)
- Canyon River (1 run)
- Campus Map (1 run)
- Calendar Month View (1 run)
- Butterfly Life Cycle (1 run)
- Exploded Burger (1 run)
- Bubble Tea (1 run)
- Breakfast Skillet (1 run)
- Boxing Ring (1 run)
- Labelled Bicycle Diagram (1 run)
- Bauhaus Composition (1 run)
- Battery Level Icons (1 run)
- Basketball Slam Dunk (1 run)
- Baseball Stadium (1 run)
- Barn Owl in Flight (1 run)
- Fruit Sales Bar Chart (1 run)
- Ballet Dancer (1 run)
- Autumn Forest Path (1 run)
- Bohr Model of an Atom (1 run)
- Stargazer with Telescope (1 run)
- Floating Astronaut (1 run)
- Art Deco Skyscraper (1 run)
- Flat App Icon Set (1 run)
- Ant Colony Cutaway (1 run)
- Illustrated Alphabet A B C (1 run)
- Alien Planet (1 run)
- Twin-Bell Alarm Clock (1 run)
- Acoustic Guitar (1 run)
- Paris Tower (1 run)
- Night Train (1 run)
- 018 Step Sequencer Grid (1 run)
- 015 Color Palette Studio (1 run)
- 014 Snake Reimagined (1 run)
- 012 Magnetic Filings (1 run)
- 010 Toggle Switch Gallery (1 run)
- 008 Pocket Theremin (1 run)
- 007 Kinetic Headline (1 run)
- 006 Rainfall Bars (1 run)
- 004 Brick Breaker Neon (1 run)
- 005 Focus Timer Orbit (1 run)
- Hummingbird at Flower (1 run)
- Corgi Catching a Frisbee (1 run)
- Polar Bear on Ice Floe (1 run)
- Hedgehog Under Mushroom (1 run)
- Wolf Howling at Moon (1 run)
- Chameleon on a Branch (1 run)
- Panda Eating Bamboo (1 run)
- Swimming Sea Turtle (1 run)
- Giraffe Side Profile (1 run)
- Octopus Juggling Teacups (1 run)
- Elephant Calf Mud Bath (1 run)
- Sleeping Curled Cat (1 run)
- Red Fox in Snow (1 run)
- 003 Orbital Coffee Landing (1 run)
- 001 Ink Bloom Garden (1 run)
- Pelican car france (1 run)
- Dolphin vlog bicycle (1 run)
- DualSense controller, max fidelity (2 runs)
- DualSense controller, quick (1 run)
- PS5 Pro console scene (1 run)
- Donut (1 run)
- Whale clouds (1 run)
- Xbox 360 controller (1 run)
- Animated pelican riding a bicycle (SMIL/CSS) (1 run)
- Pelican riding a bicycle (control) (1 run)
- Lighthouse on a headland at night (1 run)
- MacBook Pro 16" realistic 3D render (Playcode benchmark) (1 run)
- Isometric SVG town with sprite sheet (1 run)
- California brown pelican riding a bicycle (detailed spec) (1 run)
- BMW M4 Competition, side view (flat vector) (1 run)
- Cine tracking shot (1 run)
- Cine orbit 360 (1 run)
- Koi Pond Garden (1 run)
Experiment collections: HTML Files (68) · SVG (127) · Three.js (42) · Blender (1) · Harness lane (238)